PyCalendar/icalendar_compatibility
Data sources
| Repository | Pull requests | Issues | Complete | Read |
|---|---|---|---|---|
| PyCalendar/icalendar_compatibility | 2 / 2 | 8 / 8 | 100% | 1 day, 3 hours ago |
Download the data behind this page. The ODS spreadsheets also have the data each table was made from, and what the download is.
- response times: ODS, CSV, Parquet, JSON
- pull requests and issues: ODS, CSV, Parquet
- comments and reviews: ODS, CSV, Parquet
- commits: ODS, CSV, Parquet
- contributors: ODS, CSV, Parquet
How to check the numbers with scipy.
Sources shown
Response times
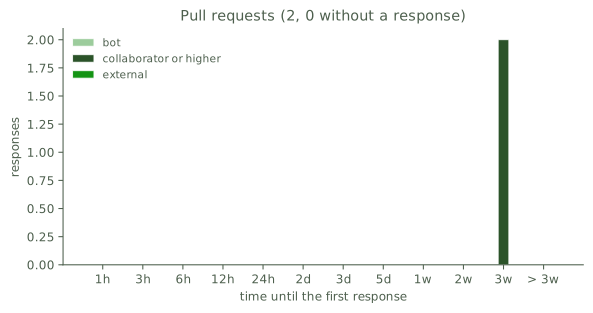
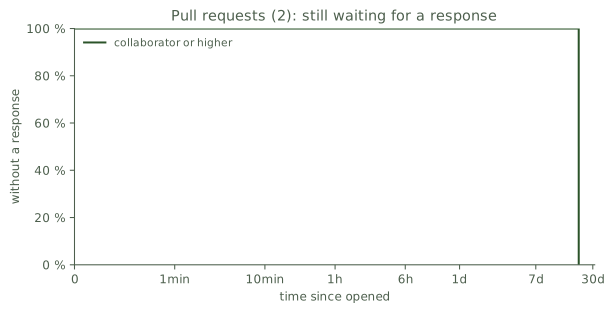
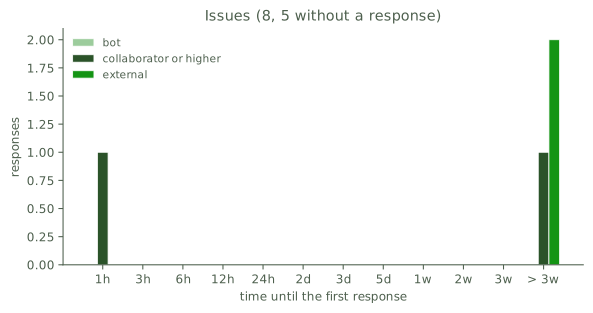
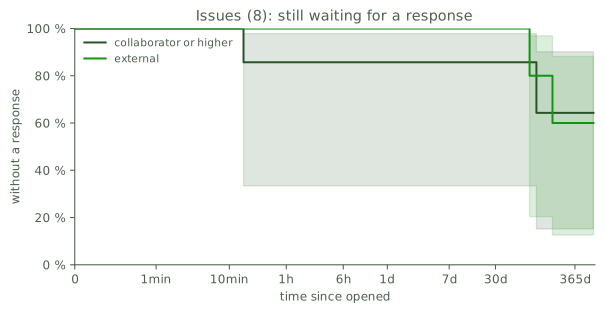
Time until the first response of each class of people (edit classes). The author's own comments do not count. Measured, normal and exponential use only the items that got a response; Kaplan-Meier counts the others, too, as waiting at least until they were closed or until now, and is "-" where less than half (or 95 %) got a response.
| class | n | fit | average | std error | median | 95% |
|---|---|---|---|---|---|---|
| collaborator or higher | 2 | measured | 20d 22h | 3min | 20d 22h | 20d 22h |
| collaborator or higher | 2 | normal | 20d 22h | 2min | 20d 22h | 20d 22h |
| collaborator or higher | 2 | exponential | 20d 22h | 14d 19h | 14d 12h | 62d 17h |
| collaborator or higher | 2 | Kaplan-Meier | - | - | 20d 22h | 20d 22h |
n counts the items with a response of the class. Kaplan-Meier counts all items, so its n is the same for every class: the items without a response of the class count as waiting, until they were closed or until now. How to read the response times
Trend: too few responses to tell whether they get faster or slower. How the trend is computed
| class | n | fit | average | std error | median | 95% |
|---|---|---|---|---|---|---|
| collaborator or higher | 2 | measured | 54d 8h | 54d 8h | 54d 8h | 103d 6h |
| collaborator or higher | 2 | normal | 54d 8h | 38d 10h | 54d 8h | 143d 18h |
| collaborator or higher | 2 | exponential | 54d 8h | 38d 10h | 37d 16h | 162d 20h |
| collaborator or higher | 8 | Kaplan-Meier | - | - | - | - |
| external | 2 | measured | 133d 23h | 46d 6h | 133d 23h | 175d 14h |
| external | 2 | normal | 133d 23h | 32d 16h | 133d 23h | 210d |
| external | 2 | exponential | 133d 23h | 94d 17h | 92d 20h | 401d 7h |
| external | 8 | Kaplan-Meier | - | - | - | - |
n counts the items with a response of the class. Kaplan-Meier counts all items, so its n is the same for every class: the items without a response of the class count as waiting, until they were closed or until now. How to read the response times
Trend: too few responses to tell whether they get faster or slower. How the trend is computed
Badges
Embed the response time in a README. The badge counts with the default classes of people. The badge shows what is in the database and never calls GitHub. Parameters: kind = pr or issue, percentile = 0-100, class = a class name (optional), model = measured, normal, exponential or kaplan-meier (optional), label = the text of the left side (optional).